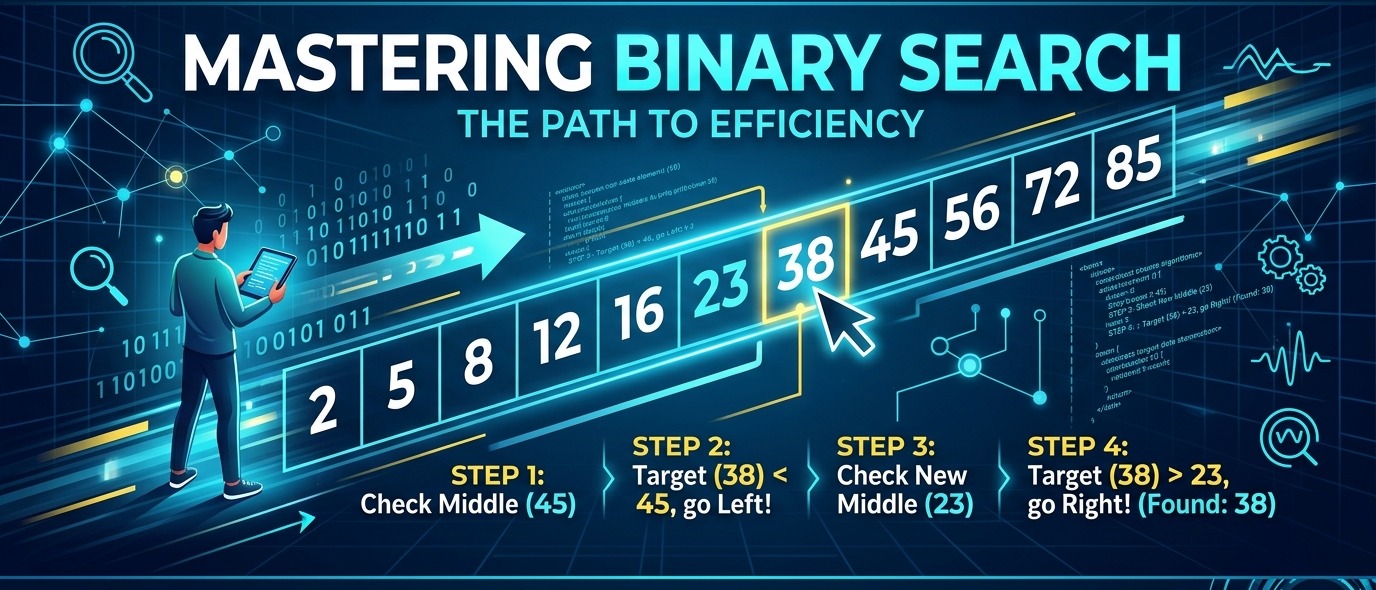
Binary Search
Binary search finds an item in a sorted list of 1,000,000 elements in at most 20 comparisons, because every comparison throws away half of the remaining candidates.
Log in to track your progress on this article.
The guessing game
Imagine a friend picks a number from 1 to 100 and you must guess it. After each guess they answer only "higher" or "lower".
A beginner guesses 1, then 2, then 3. This can take 100 guesses. A smarter player guesses 50 first. Whatever the answer, 50 numbers are gone at once. Then 25 or 75, then again half, and so on. The secret number is found in at most 7 guesses.
That smarter strategy is binary search. It is one of the most important algorithms in computer science, and it is also famously easy to get wrong. This article explains the idea, traces it by hand, gives annotated pseudocode, and shows the bugs that trip up even experienced developers.
The core idea
Binary search works only on sorted data, and it keeps a shrinking window of positions where the target could still be.
The window is described by two pointers: low (leftmost candidate) and high (rightmost candidate). Each round does three things:
Look at the middle element of the window.
If it equals the target, you are done.
If the target is smaller, the answer can only be on the left, so move
highto just before the middle. If the target is larger, movelowto just after the middle.
Why is sorting required? Because it lets one comparison say something about a whole half. If the middle value is 40 and you want 70, then everything left of the middle is also below 70. In an unsorted list that reasoning is false, and the algorithm breaks.
Before vs. after: linear search against binary search on the sorted array [3, 8, 15, 21, 34, 40, 55, 70, 89], looking for 70:
Approach | Comparisons made | Idea |
|---|---|---|
Linear search | 8 (checks 3, 8, 15, 21, 34, 40, 55, then 70) | Walk from the left, one item at a time |
Binary search | 3 (checks 34, 55, then 70) | Jump to the middle, discard half each time |
On 9 items the gap is small. On a million items it is 1,000,000 against 20.
A worked example, step by step
Search for 70 in this sorted array. Positions (indices) start at 0:
Index | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 |
|---|---|---|---|---|---|---|---|---|---|
Value | 3 | 8 | 15 | 21 | 34 | 40 | 55 | 70 | 89 |
The middle index is mid = (low + high) / 2, rounded down.
Round | low | high | mid | Value at mid | Decision | Candidates left |
|---|---|---|---|---|---|---|
1 | 0 | 8 | 4 | 34 | 34 < 70, so go right: | 4 (indices 5 to 8) |
2 | 5 | 8 | 6 | 55 | 55 < 70, so go right: | 2 (indices 7 to 8) |
3 | 7 | 8 | 7 | 70 | Found it. Return index 7 | done |
Notice what happened to the window: 9 candidates, then 4, then 2, then the answer. It roughly halves every round.
What if the target is missing? Search for 50 in the same array. The window keeps shrinking until low passes high: round 1 checks 34 (go right, low = 5), round 2 checks 55 (go left, high = 5), round 3 checks 40 (go right, low = 6). Now low = 6 is greater than high = 5, so the window is empty. The algorithm stops and reports "not found".
The algorithm in pseudocode
Here is the iterative version, the one used most in practice, with every line explained.
function binarySearch(arr, target):
    low  = 0                      // (1) leftmost index still possible
    high = length(arr) - 1        // (2) rightmost index still possible

    while low <= high:            // (3) window is non-empty
        mid = low + (high - low) / 2   // (4) middle, written overflow-safe

        if arr[mid] == target:    // (5) lucky hit
            return mid
        else if arr[mid] < target:   // (6) middle too small
            low = mid + 1         //     discard mid and everything left of it
        else:                     // (7) middle too big
            high = mid - 1        //     discard mid and everything right of it

    return NOT_FOUND              // (8) window became empty (low > high)
Reading it like a teacher would:
(1) and (2) start the window as the whole array.
(3) uses
<=, not<. Whenlow == highthere is still exactly one candidate left, and it must be checked.(4) is the same as
(low + high) / 2in math, but safer in languages with fixed-size integers (see the bugs section).(6) and (7) move a pointer to
mid + 1ormid - 1, never tomiditself. We already checkedmid, so we can exclude it. This is what guarantees the window shrinks every round.(8) is reached only when the window is empty, so the target is not in the array.
Recursive version
The same idea, expressed as "solve a smaller version of the same problem":
function search(arr, target, low, high):
    if low > high:                // base case: empty window
        return NOT_FOUND
    mid = low + (high - low) / 2
    if arr[mid] == target:
        return mid
    if arr[mid] < target:
        return search(arr, target, mid + 1, high)   // right half
    return search(arr, target, low, mid - 1)        // left half
Both versions do the same work. The iterative one uses constant extra memory. The recursive one uses about log2(n) stack frames, which is tiny but not zero.
Three classic bugs (and their fixes)
The idea takes a minute to learn. Writing it correctly takes practice. Jon Bentley reported that most professional programmers he tested wrote a buggy version, and a famous overflow bug survived for years in widely used library code. Here are the three most common mistakes, each shown as before and after.
Bug 1: integer overflow in the midpoint
Before (buggy):
mid = (low + high) / 2If low and high are both near the maximum value of a 32-bit integer (about 2.1 billion), their sum exceeds that maximum and wraps around to a negative number. mid becomes garbage and the program crashes or loops. This needs an array of roughly a billion elements, so it was hidden for years, but it is real.
After (fixed):
mid = low + (high - low) / 2high - low can never overflow, and adding half of it to low stays inside the range.
Bug 2: an off-by-one in the loop condition
Before (buggy):
while low < high: // stops when one candidate is leftSearching [5] for 5: low = high = 0, so the loop never runs and the function wrongly says "not found".
After (fixed):
while low <= high: // checks the last remaining candidate tooBug 3: an infinite loop from a lazy pointer update
Before (buggy):
else if arr[mid] < target:
    low = mid            // mid was already checked, but stays in the window
With low = 4, high = 5, mid is 4. If arr[4] < target, then low stays 4 and the next round is identical. It repeats forever.
After (fixed):
else if arr[mid] < target:
    low = mid + 1        // window is guaranteed to shrink
The rule behind all three: keep an invariant in your head: "if the target exists, it lies inside [low, high]." Every update must keep that true while making the window strictly smaller.
Why it is O(log n)
Binary search takes O(log n) time: the number of steps grows with the logarithm of the array size, not with the size itself.
The reasoning is short. Start with n candidates. After one round at most n/2 remain, after two rounds n/4, after k rounds n/2^k. The search must stop when one candidate (or none) is left:
So the worst case is about log2(n) + 1 comparisons. In plain words: how many times can you halve n before you reach 1? That count is the logarithm.
Here is how slowly that number grows, compared with the worst case of linear search:
Array size (n) | Linear search, worst case | Binary search, worst case |
|---|---|---|
10 | 10 | 4 |
100 | 100 | 7 |
1,000 | 1,000 | 10 |
1,000,000 | 1,000,000 | 20 |
1,000,000,000 | 1,000,000,000 | 30 |
1,000,000,000,000 | 1,000,000,000,000 | 40 |
Doubling the data adds only one extra step. That is the whole magic.
Space complexity is O(1) for the iterative version (only low, high, mid) and O(log n) for the recursive one, because of the call stack.
One honest caveat: the O(log n) cost assumes the data is already sorted and that you can jump to any position instantly (random access, as in an array). Sorting first costs O(n log n), so for a single search on unsorted data a plain linear scan is cheaper. Binary search pays off when you search the same data many times.
Useful variants
The basic version answers "is it there?". Real problems usually ask something slightly different.
Variant 1: first occurrence (lower bound)
With duplicates, such as [1, 2, 2, 2, 3], the basic version may return any of the 2s. To find the first index whose value is at least the target, do not stop on a match. Remember it and keep searching left:
function lowerBound(arr, target):
    low = 0
    high = length(arr) - 1
    answer = NOT_FOUND

    while low <= high:
        mid = low + (high - low) / 2
        if arr[mid] >= target:    // mid could be the answer...
            answer = mid          // ...so remember it
            high = mid - 1        // ...but look for an earlier one
        else:
            low = mid + 1

    return answer                 // first index with arr[i] >= target
For [1, 2, 2, 2, 3] and target 2, this returns index 1. Flip the comparison (arr[mid] > target) and it returns the first element strictly greater, the upper bound. The distance between the two bounds counts how many copies exist.
Variant 2: binary search on the answer
The most powerful idea: you do not need an array at all. You need a yes/no question whose answer flips exactly once as a number grows.
Example: "What is the smallest speed that lets a delivery truck finish in 8 hours?" The check "can it finish at speed s?" is false for small s and true for large s. That is a sorted sequence of false, false, ..., true, true, so you can binary search over s:
function smallestGoodSpeed():
    low = 1
    high = MAX_SPEED
    while low < high:
        mid = low + (high - low) / 2
        if canFinish(mid):        // works, so the answer is mid or smaller
            high = mid
        else:                     // too slow, so the answer is larger
            low = mid + 1
    return low
Notice this loop uses low < high and high = mid. That is a different, equally valid style: the window always contains the answer, and the loop ends when it has one element. Pick one style per problem and keep its invariant consistent.
Variant 3: debugging with git bisect
If a bug appeared somewhere in 1,000 commits, git bisect checks the middle commit, you say "good" or "bad", and it halves the range. You find the guilty commit in about 10 steps.
Where it is used, and where it is not
Binary search hides inside many everyday tools:
Libraries:
Arrays.binarySearchin Java,bisectin Python,std::lower_boundin C++.Databases: B-tree indexes in SQL databases (including Oracle and PostgreSQL) narrow down rows with the same halving idea, adapted to disk pages.
Debugging:
git bisect, as described above.Optimization problems: finding minimum capacity, speed or time under a constraint (binary search on the answer).
Games and tuning: "guess my number", difficulty calibration, finding a threshold value.
It is a poor fit in these cases:
Situation | Why binary search fails | Better choice |
|---|---|---|
Unsorted data, searched once | Sorting costs O(n log n), more than one O(n) scan | Linear search |
Linked list | No instant access to the middle, so finding | Linear search, or a different structure |
Data that changes constantly | Keeping the array sorted on every insert is expensive | Balanced tree or hash table |
Exact-match lookups only, very frequent | Hashing answers in O(1) on average | Hash table |
Summary and practice
Binary search finds a target in sorted data in O(log n) time by repeatedly comparing with the middle and discarding the half that cannot contain it.
What to remember:
The data must be sorted and support fast random access.
Keep the invariant: if the target exists, it is inside
[low, high].Compute
mid = low + (high - low) / 2to avoid overflow.Move pointers to
mid + 1ormid - 1, never leave them onmid.For "first/last occurrence" or "smallest value that works", do not stop on a match; record it and keep narrowing.
Practice problems, from easy to harder:
Implement the iterative version and test on: empty array, one element, target at the first position, at the last position, and missing on both ends.
Return the first and last index of a value in an array with duplicates.
Compute the integer square root of
nusing binary search on the answer.Search in a sorted array that was rotated, such as
[40, 55, 70, 3, 8, 15].Find the minimum capacity of a ship that delivers all packages within D days.